Video
FLUX 3 Max Image to Video Variantes: 3
desde $0.0425 / segundo de video de salida
42.5 créditos de API / segundo de video de salida · ≈ ₽4.57
No hay coincidencias. Prueba con “video”, “FLUX” o “webhooks”.
Cargando modelos…
blackforestlabs/flux-3-max/text-to-video
# Run the model; wait up to 20 s for the finished result in the same call
curl -X POST "https://api.doitong.ru/v1/run/blackforestlabs/flux-3-max/text-to-video?wait=20" \
  -H "Authorization: Bearer $DOITONG_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "prompt": "Four-way CCTV-style split-screen showing the same real-time event inside a convenience shop. Divide the frame into four equal security-camera views with timestamps. Top left: wide ceiling-corner view covering aisles, entrance, and cashier. Top right: overhead view above the central aisle. Bottom left: camera facing the checkout counter. Bottom right: camera near the entrance looking inward. At the 2-second mark, a customer takes a boxed item from a shelf, accidentally bumps a display, catches one falling bottle, then places the box on the checkout counter. The cashier turns, scans it, and hands over a receipt as another shopper crosses behind them. All four views must remain perfectly synchronized, showing identical people, movements, object positions, occlusions, timestamps, lighting, and physical reactions. Use realistic low-resolution CCTV footage, slight lens distortion, fixed cameras, and no cinematic camera movement.",
    "duration": 5,
    "resolution": "720p",
    "aspect_ratio": "16:9",
    "generate_audio": false
  }'

# Still "queued" or "running"? Poll with the id from the response:
curl "https://api.doitong.ru/v1/requests/REQUEST_ID?wait=20" \
  -H "Authorization: Bearer $DOITONG_API_KEY"
const API = "https://api.doitong.ru/v1";
const headers = {
"Authorization": "Bearer " + process.env.DOITONG_API_KEY,
"Content-Type": "application/json",
};
// Run the model; wait up to 20 s for the finished result in the same call
let res = await fetch(API + "/run/blackforestlabs/flux-3-max/text-to-video?wait=20", {
method: "POST",
headers,
body: JSON.stringify({
"prompt": "Four-way CCTV-style split-screen showing the same real-time event inside a convenience shop. Divide the frame into four equal security-camera views with timestamps. Top left: wide ceiling-corner view covering aisles, entrance, and cashier. Top right: overhead view above the central aisle. Bottom left: camera facing the checkout counter. Bottom right: camera near the entrance looking inward. At the 2-second mark, a customer takes a boxed item from a shelf, accidentally bumps a display, catches one falling bottle, then places the box on the checkout counter. The cashier turns, scans it, and hands over a receipt as another shopper crosses behind them. All four views must remain perfectly synchronized, showing identical people, movements, object positions, occlusions, timestamps, lighting, and physical reactions. Use realistic low-resolution CCTV footage, slight lens distortion, fixed cameras, and no cinematic camera movement.",
"duration": 5,
"resolution": "720p",
"aspect_ratio": "16:9",
"generate_audio": false
}),
});
let request = await res.json();
if (!res.ok) throw new Error(request.error.code + ": " + request.error.message);
// Not finished yet: long-poll until it is
while (request.status === "queued" || request.status === "running") {
res = await fetch(API + "/requests/" + request.id + "?wait=20", { headers });
request = await res.json();
}
if (request.status !== "succeeded") throw new Error(JSON.stringify(request.error));
console.log(request.outputs.map((o) => o.url), request.cost.credits + " API credits ($" + request.cost.usd + ")");import os
import requests
API = "https://api.doitong.ru/v1"
headers = {"Authorization": "Bearer " + os.environ["DOITONG_API_KEY"]}
payload = {
"prompt": "Four-way CCTV-style split-screen showing the same real-time event inside a convenience shop. Divide the frame into four equal security-camera views with timestamps. Top left: wide ceiling-corner view covering aisles, entrance, and cashier. Top right: overhead view above the central aisle. Bottom left: camera facing the checkout counter. Bottom right: camera near the entrance looking inward. At the 2-second mark, a customer takes a boxed item from a shelf, accidentally bumps a display, catches one falling bottle, then places the box on the checkout counter. The cashier turns, scans it, and hands over a receipt as another shopper crosses behind them. All four views must remain perfectly synchronized, showing identical people, movements, object positions, occlusions, timestamps, lighting, and physical reactions. Use realistic low-resolution CCTV footage, slight lens distortion, fixed cameras, and no cinematic camera movement.",
"duration": 5,
"resolution": "720p",
"aspect_ratio": "16:9",
"generate_audio": False,
}
# Run the model; wait up to 20 s for the finished result in the same call
r = requests.post(API + "/run/blackforestlabs/flux-3-max/text-to-video", params={"wait": 20}, json=payload, headers=headers)
request = r.json()
if not r.ok:
raise RuntimeError(request["error"]["code"] + ": " + request["error"]["message"])
# Not finished yet: long-poll until it is
while request["status"] in ("queued", "running"):
request = requests.get(API + "/requests/" + request["id"], params={"wait": 20}, headers=headers).json()
if request["status"] != "succeeded":
raise RuntimeError(request["error"])
print([o["url"] for o in request["outputs"]], request["cost"]["credits"], "API credits", "$" + request["cost"]["usd"])# 1. Connect once (Claude Code; Cursor, VS Code, Claude Desktop: https://doitong.com/es-MX/developers/docs/mcp)
claude mcp add --transport http doitong-models https://api.doitong.ru/v1/mcp \
--header "Authorization: Bearer $DOITONG_API_KEY"
# 2. Your agent calls the "run" tool with:
{
"model_id": "blackforestlabs/flux-3-max/text-to-video",
"input": {
"prompt": "Four-way CCTV-style split-screen showing the same real-time event inside a convenience shop. Divide the frame into four equal security-camera views with timestamps. Top left: wide ceiling-corner view covering aisles, entrance, and cashier. Top right: overhead view above the central aisle. Bottom left: camera facing the checkout counter. Bottom right: camera near the entrance looking inward. At the 2-second mark, a customer takes a boxed item from a shelf, accidentally bumps a display, catches one falling bottle, then places the box on the checkout counter. The cashier turns, scans it, and hands over a receipt as another shopper crosses behind them. All four views must remain perfectly synchronized, showing identical people, movements, object positions, occlusions, timestamps, lighting, and physical reactions. Use realistic low-resolution CCTV footage, slight lens distortion, fixed cameras, and no cinematic camera movement.",
"duration": 5,
"resolution": "720p",
"aspect_ratio": "16:9",
"generate_audio": false
}
}Llama al modelo FLUX 3 Max Text to Video (blackforestlabs/flux-3-max/text-to-video) mediante Doitong API. Documentación para agentes: https://doitong.com/es-MX/developers/models/blackforestlabs/flux-3-max/text-to-video.md
POST https://api.doitong.ru/v1/run/blackforestlabs/flux-3-max/text-to-video?wait=20
Authorization: Bearer $DOITONG_API_KEY
Content-Type: application/json
{
"prompt": "Four-way CCTV-style split-screen showing the same real-time event inside a convenience shop. Divide the frame into four equal security-camera views with timestamps. Top left: wide ceiling-corner view covering aisles, entrance, and cashier. Top right: overhead view above the central aisle. Bottom left: camera facing the checkout counter. Bottom right: camera near the entrance looking inward. At the 2-second mark, a customer takes a boxed item from a shelf, accidentally bumps a display, catches one falling bottle, then places the box on the checkout counter. The cashier turns, scans it, and hands over a receipt as another shopper crosses behind them. All four views must remain perfectly synchronized, showing identical people, movements, object positions, occlusions, timestamps, lighting, and physical reactions. Use realistic low-resolution CCTV footage, slight lens distortion, fixed cameras, and no cinematic camera movement.",
"duration": 5,
"resolution": "720p",
"aspect_ratio": "16:9",
"generate_audio": false
}
Si el estado de la respuesta es "queued" o "running", consulta GET https://api.doitong.ru/v1/requests/REQUEST_ID?wait=20 hasta que sea "succeeded"; los archivos están en outputs[].url. POST https://api.doitong.ru/v1/quote/blackforestlabs/flux-3-max/text-to-video con el mismo cuerpo devuelve el precio exacto antes de la ejecución.Archivos como el ejemplo: $0.425 425 créditos de API · ≈ ₽45.67 tus archivos se miden antes de la ejecución Ejecutar en esta página
Tu nueva clave de API. Solo se muestra ahora y ya está en el código y en el campo de clave de API de abajo. Mantenla en secreto: nunca la incluyas en código que se ejecute en un navegador.
PromptFour-way CCTV-style split-screen showing the same real-time event inside a convenience shop. Divide the frame into four equal security-camera views with timestamps. Top left: wide ceiling-corner view covering aisles, entrance, and cashier. Top right: overhead view above the central aisle. Bottom left: camera facing the checkout counter. Bottom right: camera near the entrance looking inward. At the 2-second mark, a customer takes a boxed item from a shelf, accidentally bumps a display, catches one falling bottle, then places the box on the checkout counter. The cashier turns, scans it, and hands over a receipt as another shopper crosses behind them. All four views must remain perfectly synchronized, showing identical people, movements, object positions, occlusions, timestamps, lighting, and physical reactions. Use realistic low-resolution CCTV footage, slight lens distortion, fixed cameras, and no cinematic camera movement.
Los controles se generan a partir del esquema del modelo. El código y el precio se actualizan conforme los cambias.
/run/blackforestlabs/flux-3-max/text-to-video?wait=20
cotización → $0.425
# Run the model; wait up to 20 s for the finished result in the same call
curl -X POST "https://api.doitong.ru/v1/run/blackforestlabs/flux-3-max/text-to-video?wait=20" \
  -H "Authorization: Bearer $DOITONG_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "prompt": "Four-way CCTV-style split-screen showing the same real-time event inside a convenience shop. Divide the frame into four equal security-camera views with timestamps. Top left: wide ceiling-corner view covering aisles, entrance, and cashier. Top right: overhead view above the central aisle. Bottom left: camera facing the checkout counter. Bottom right: camera near the entrance looking inward. At the 2-second mark, a customer takes a boxed item from a shelf, accidentally bumps a display, catches one falling bottle, then places the box on the checkout counter. The cashier turns, scans it, and hands over a receipt as another shopper crosses behind them. All four views must remain perfectly synchronized, showing identical people, movements, object positions, occlusions, timestamps, lighting, and physical reactions. Use realistic low-resolution CCTV footage, slight lens distortion, fixed cameras, and no cinematic camera movement.",
    "duration": 5,
    "resolution": "720p",
    "aspect_ratio": "16:9",
    "generate_audio": false
  }'

# Still "queued" or "running"? Poll with the id from the response:
curl "https://api.doitong.ru/v1/requests/REQUEST_ID?wait=20" \
  -H "Authorization: Bearer $DOITONG_API_KEY"
const API = "https://api.doitong.ru/v1";
const headers = {
"Authorization": "Bearer " + process.env.DOITONG_API_KEY,
"Content-Type": "application/json",
};
// Run the model; wait up to 20 s for the finished result in the same call
let res = await fetch(API + "/run/blackforestlabs/flux-3-max/text-to-video?wait=20", {
method: "POST",
headers,
body: JSON.stringify({
"prompt": "Four-way CCTV-style split-screen showing the same real-time event inside a convenience shop. Divide the frame into four equal security-camera views with timestamps. Top left: wide ceiling-corner view covering aisles, entrance, and cashier. Top right: overhead view above the central aisle. Bottom left: camera facing the checkout counter. Bottom right: camera near the entrance looking inward. At the 2-second mark, a customer takes a boxed item from a shelf, accidentally bumps a display, catches one falling bottle, then places the box on the checkout counter. The cashier turns, scans it, and hands over a receipt as another shopper crosses behind them. All four views must remain perfectly synchronized, showing identical people, movements, object positions, occlusions, timestamps, lighting, and physical reactions. Use realistic low-resolution CCTV footage, slight lens distortion, fixed cameras, and no cinematic camera movement.",
"duration": 5,
"resolution": "720p",
"aspect_ratio": "16:9",
"generate_audio": false
}),
});
let request = await res.json();
if (!res.ok) throw new Error(request.error.code + ": " + request.error.message);
// Not finished yet: long-poll until it is
while (request.status === "queued" || request.status === "running") {
res = await fetch(API + "/requests/" + request.id + "?wait=20", { headers });
request = await res.json();
}
if (request.status !== "succeeded") throw new Error(JSON.stringify(request.error));
console.log(request.outputs.map((o) => o.url), request.cost.credits + " API credits ($" + request.cost.usd + ")");import os
import requests
API = "https://api.doitong.ru/v1"
headers = {"Authorization": "Bearer " + os.environ["DOITONG_API_KEY"]}
payload = {
"prompt": "Four-way CCTV-style split-screen showing the same real-time event inside a convenience shop. Divide the frame into four equal security-camera views with timestamps. Top left: wide ceiling-corner view covering aisles, entrance, and cashier. Top right: overhead view above the central aisle. Bottom left: camera facing the checkout counter. Bottom right: camera near the entrance looking inward. At the 2-second mark, a customer takes a boxed item from a shelf, accidentally bumps a display, catches one falling bottle, then places the box on the checkout counter. The cashier turns, scans it, and hands over a receipt as another shopper crosses behind them. All four views must remain perfectly synchronized, showing identical people, movements, object positions, occlusions, timestamps, lighting, and physical reactions. Use realistic low-resolution CCTV footage, slight lens distortion, fixed cameras, and no cinematic camera movement.",
"duration": 5,
"resolution": "720p",
"aspect_ratio": "16:9",
"generate_audio": False,
}
# Run the model; wait up to 20 s for the finished result in the same call
r = requests.post(API + "/run/blackforestlabs/flux-3-max/text-to-video", params={"wait": 20}, json=payload, headers=headers)
request = r.json()
if not r.ok:
raise RuntimeError(request["error"]["code"] + ": " + request["error"]["message"])
# Not finished yet: long-poll until it is
while request["status"] in ("queued", "running"):
request = requests.get(API + "/requests/" + request["id"], params={"wait": 20}, headers=headers).json()
if request["status"] != "succeeded":
raise RuntimeError(request["error"])
print([o["url"] for o in request["outputs"]], request["cost"]["credits"], "API credits", "$" + request["cost"]["usd"]){
"jsonrpc": "2.0",
"id": 1,
"method": "tools/call",
"params": {
"name": "run",
"arguments": {
"model_id": "blackforestlabs/flux-3-max/text-to-video",
"input": {
"prompt": "Four-way CCTV-style split-screen showing the same real-time event inside a convenience shop. Divide the frame into four equal security-camera views with timestamps. Top left: wide ceiling-corner view covering aisles, entrance, and cashier. Top right: overhead view above the central aisle. Bottom left: camera facing the checkout counter. Bottom right: camera near the entrance looking inward. At the 2-second mark, a customer takes a boxed item from a shelf, accidentally bumps a display, catches one falling bottle, then places the box on the checkout counter. The cashier turns, scans it, and hands over a receipt as another shopper crosses behind them. All four views must remain perfectly synchronized, showing identical people, movements, object positions, occlusions, timestamps, lighting, and physical reactions. Use realistic low-resolution CCTV footage, slight lens distortion, fixed cameras, and no cinematic camera movement.",
"duration": 5,
"resolution": "720p",
"aspect_ratio": "16:9",
"generate_audio": false
},
"wait_seconds": 20
}
}
}Tu clave permanece en este navegador: solo se envía a la Doitong API y se guarda en localStorage únicamente si marcas Recordar. Obtener una clave de API
Trabajos públicos creados con FLUX 3 Max por la comunidad de Doitong. Reutiliza un prompt con un clic.
Close-up portrait seorang wanita berkulit pucat berdiri setengah tubuh di dalam air berwarna lembut kebiruan, dikelilingi bunga teratai berkelopak penuh yang bermekaran indah di permukaan air. Rambutnya pirang pucat tersanggul longgar dengan beberapa helaian tipis jatuh alami membingkai sisi...
Close-up portrait seorang wanita berkulit pucat berdiri setengah tubuh di dalam air berwarna lembut kebiruan, dikelilingi bunga teratai berkelopak penuh yang bermekaran indah di permukaan air. Rambutnya pirang pucat tersanggul longgar dengan beberapa helaian tipis jatuh alami membingkai sisi...
Prompt Details Seorang wanita berkulit pucat berdiri setengah tubuh di dalam air berwarna lembut kebiruan, dikelilingi bunga teratai berkelopak penuh yang bermekaran indah di permukaan air. Rambutnya pirang pucat tersanggul longgar dengan beberapa helaian tipis jatuh alami membingkai sisi...
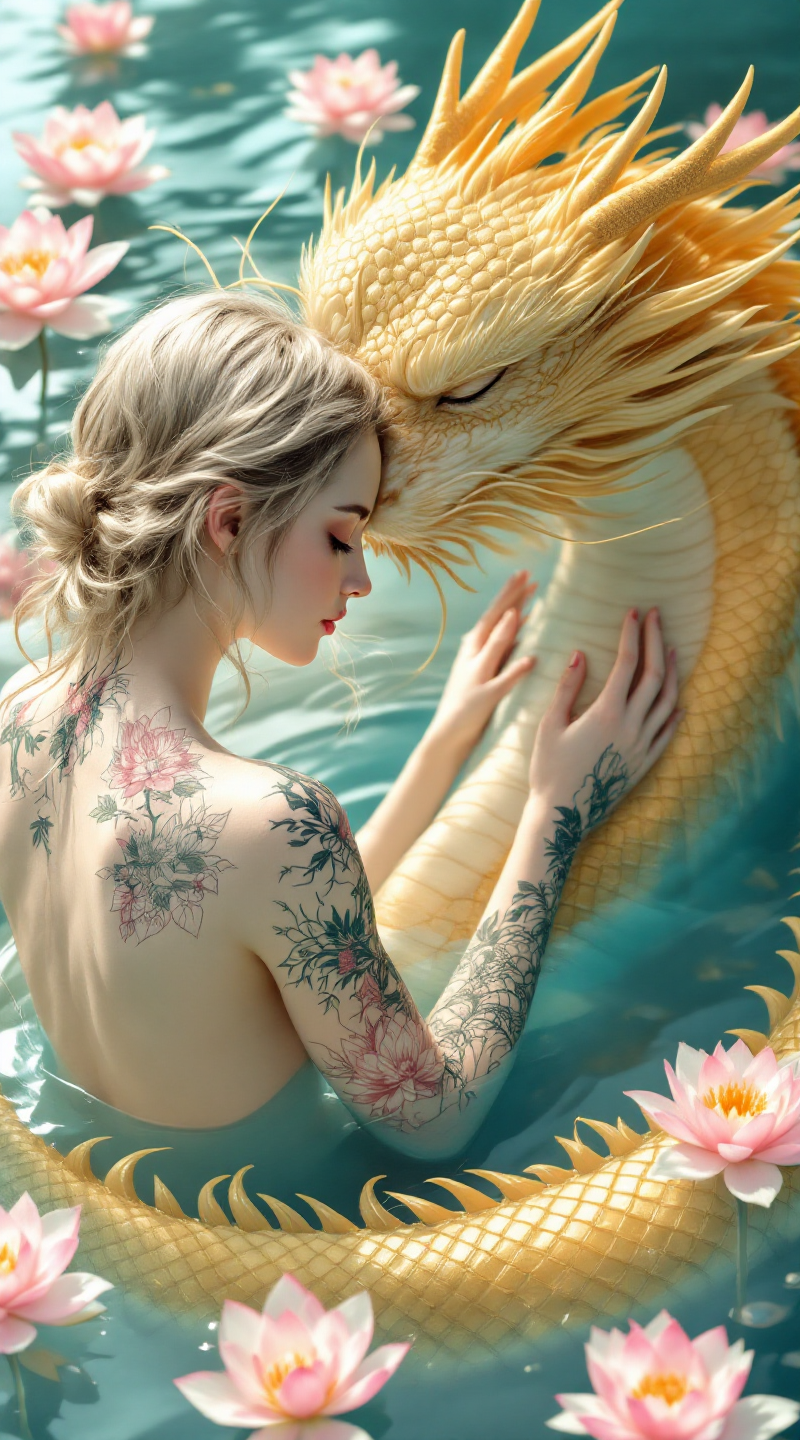
Seorang wanita berkulit pucat berdiri setengah tubuh di dalam air berwarna lembut kebiruan, dikelilingi bunga teratai berkelopak penuh yang bermekaran indah di permukaan air. Rambutnya pirang pucat tersanggul longgar dengan beberapa helaian tipis jatuh alami membingkai sisi wajahnya. Ia memeluk...
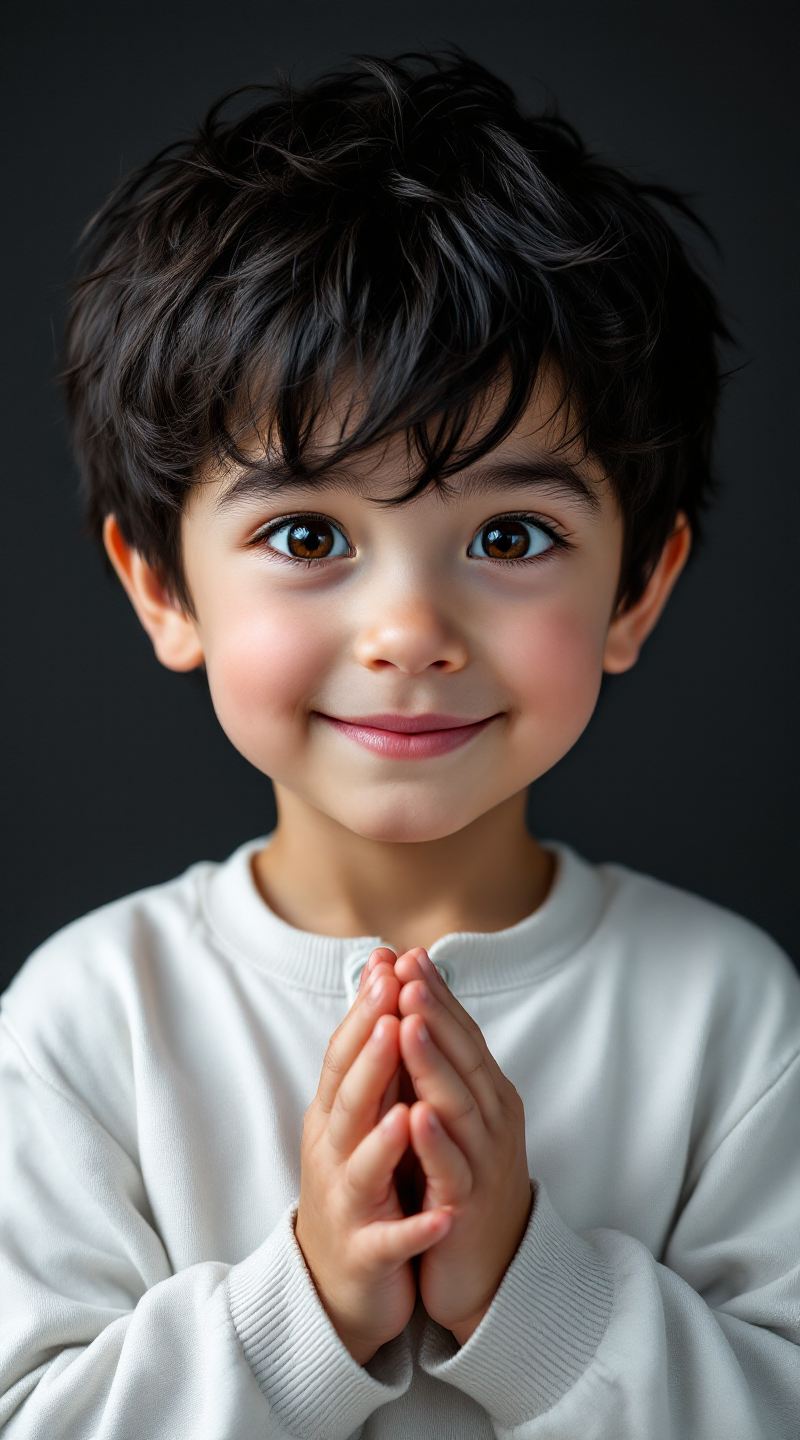
"Potret sinematik ultra-realistis close-up seorang anak laki-laki kecil (balita) yang sangat menggemaskan dengan mata cokelat besar yang ekspresif, rambut hitam berantakan yang tebal, mengenakan kaus putih kerah henley. Dia berpose dengan kedua tangan terkatup di depan dada, menunjukkan senyum...
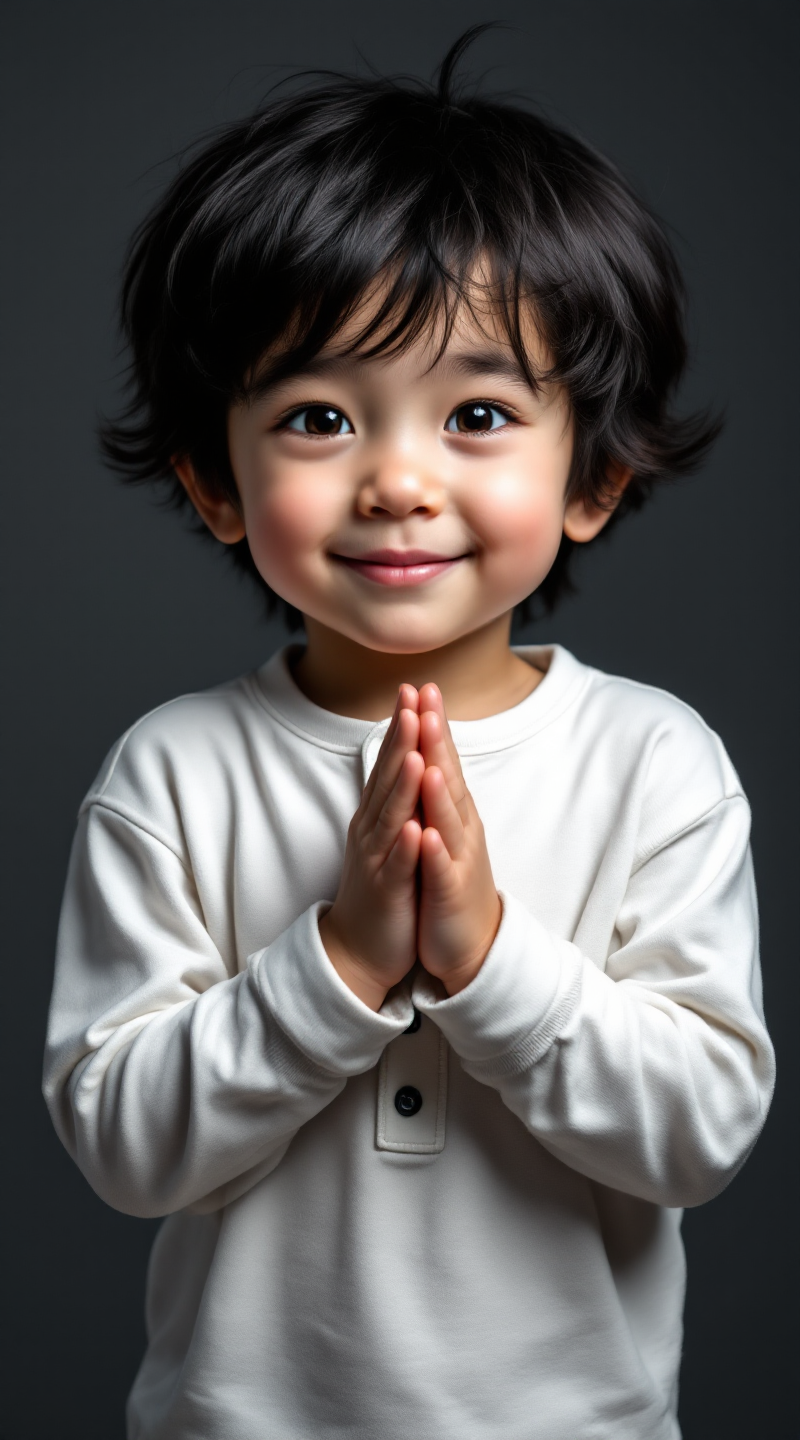
"Potret sinematik ultra-realistis close-up seorang anak laki-laki kecil (balita) yang sangat menggemaskan dengan mata cokelat besar yang ekspresif, rambut hitam berantakan yang tebal, mengenakan kaus putih kerah henley. Dia berpose dengan kedua tangan terkatup di depan dada, menunjukkan senyum...
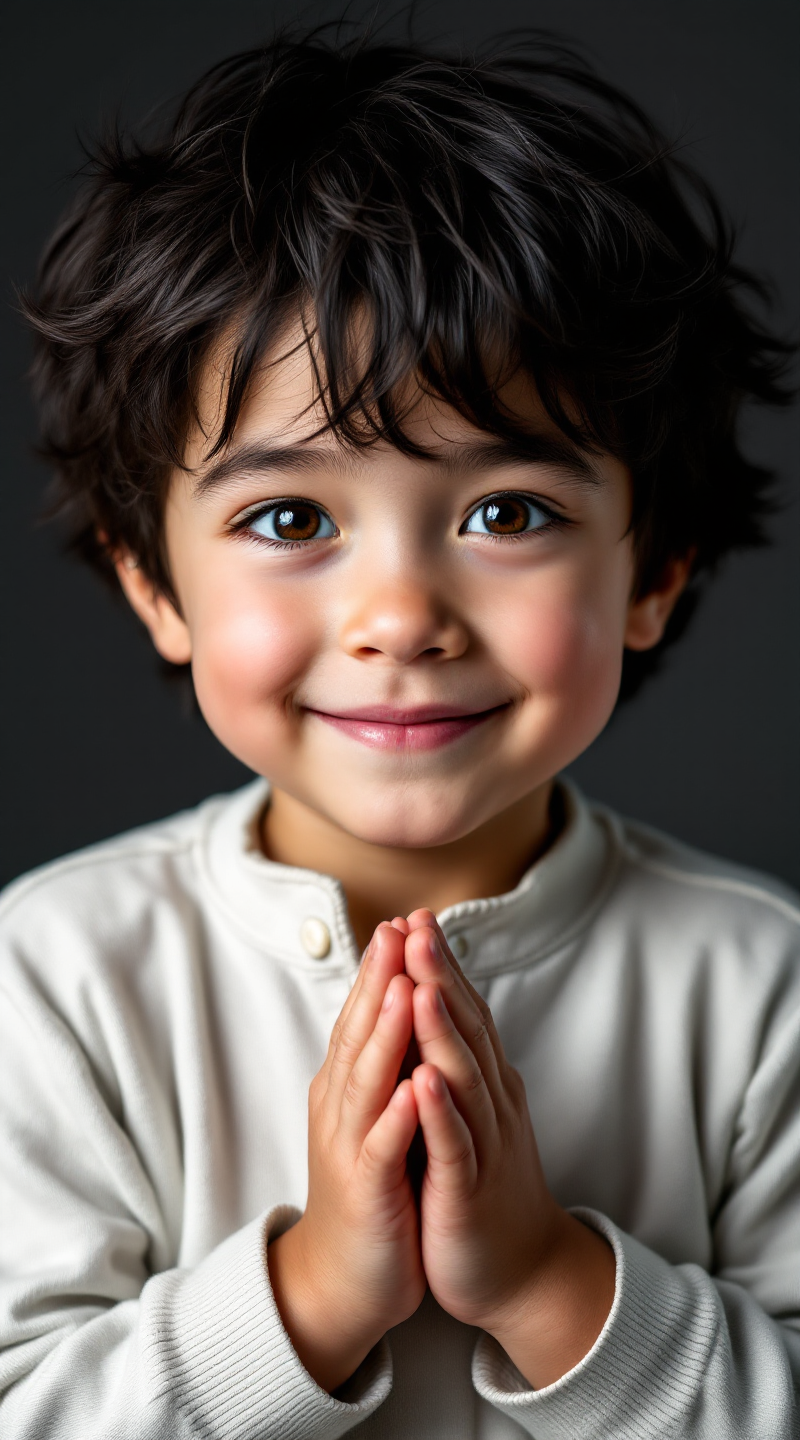
"Potret sinematik ultra-realistis close-up seorang anak laki-laki kecil (balita) yang sangat menggemaskan dengan mata cokelat besar yang ekspresif, rambut hitam berantakan yang tebal, mengenakan kaus putih kerah henley. Dia berpose dengan kedua tangan terkatup di depan dada, menunjukkan senyum...
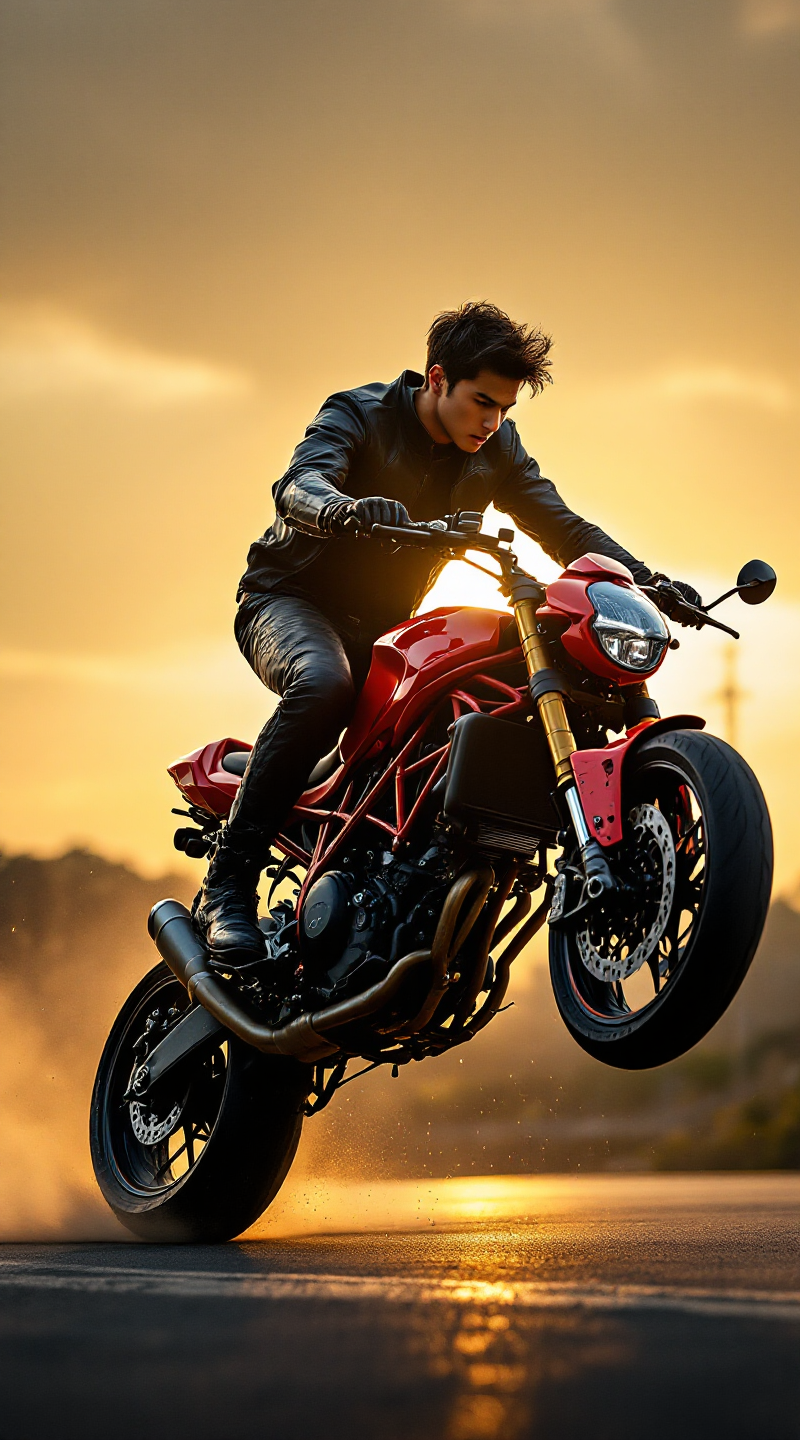
Foto sinematik hiper-realistis resolusi tinggi menampilkan seorang pria muda Indonesia dengan tubuh ramping dan proporsional, rambut hitam pendek agak acak, mengenakan jaket kulit hitam, celana riding fit, dan sepatu motor. Ia sedang melakukan aksi freestyle ekstrem dengan motor sport 500cc...
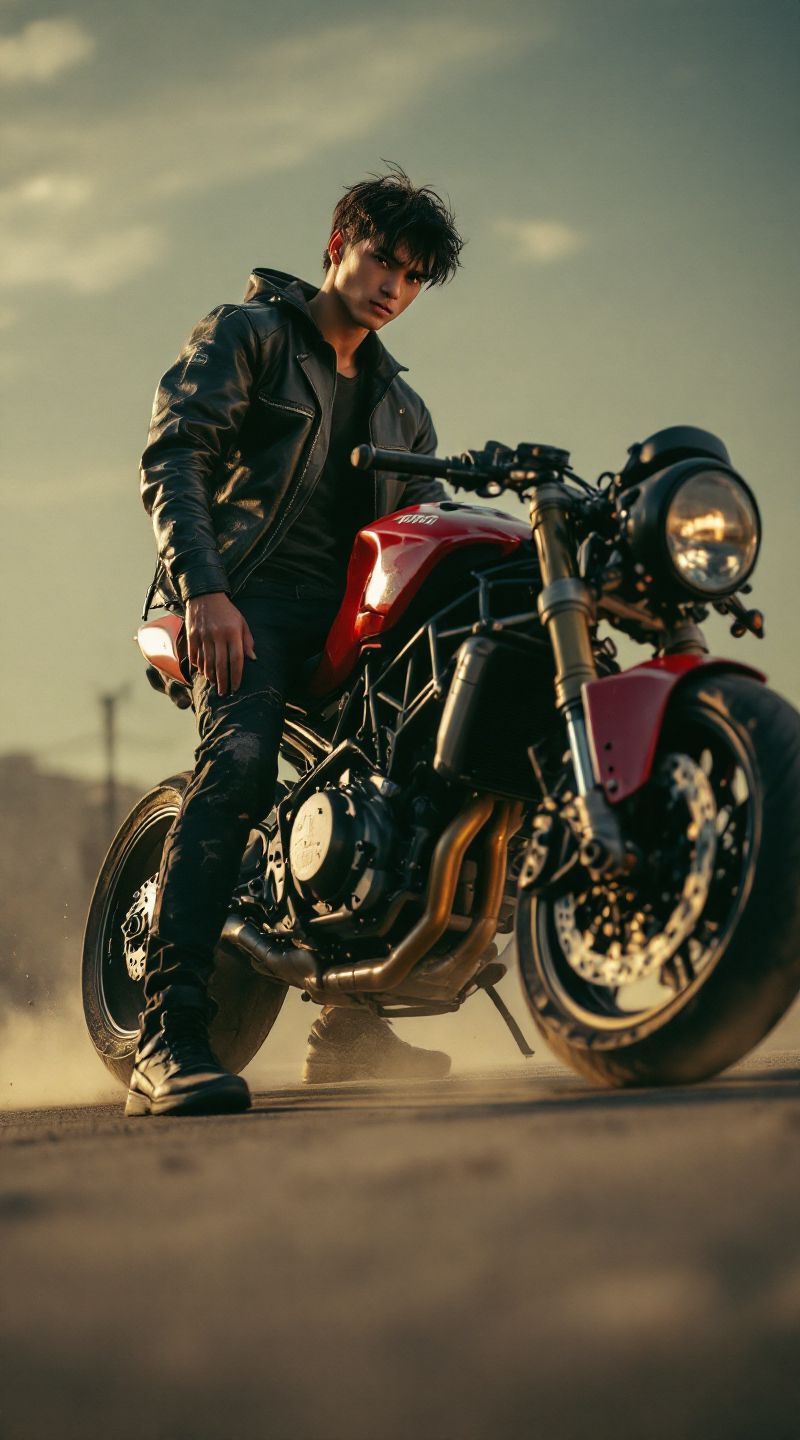
Foto sinematik hiper-realistis resolusi tinggi menampilkan seorang pria muda Indonesia dengan tubuh ramping dan proporsional, rambut hitam pendek agak acak, mengenakan jaket kulit hitam dan celana riding fit. Ia sedang bersiap melakukan freestyle menggunakan motor sport 500cc berwarna merah,...
FLUX 3 Max lleva el estilo de FLUX al video: fotogramas detallados y bien iluminados, movimiento natural y audio generado. Razonasobre el prompt antes del renderizado (esfuerzo alto o bajo), admite clips de 5 a 20 segundos y ocho relaciones de aspecto de 9:16 a 21:9, en 720p o 1080p. Una semilla hace que las ejecuciones sean repetibles.
promptobligatorio
durationopcional
resolutionopcional
reasoning_levelopcional
aspect_ratioopcional
generate_audioopcional
seedopcional
{
  "id": "req_8k2m4q7x1z9c3v5b6n0p2r4t",
  "object": "request",
  "model": "blackforestlabs/flux-3-max/text-to-video",
  "status": "succeeded",
  "created_at": "2026-10-20T12:00:00Z",
  "started_at": "2026-10-20T12:00:02Z",
  "completed_at": "2026-10-20T12:00:09Z",
  "queue_position": null,
  "cost": {
    "credits": 425,
    "usd": "0.425",
    "charged": 425,
    "refunded": 0
  },
  "input": {
    "prompt": "A red panda walks along a mossy log in a sunlit forest, pauses to sniff the air, then climbs over a branch",
    "duration": 5,
    "resolution": "720p"
  },
  "output": {
    "video": {
      "url": "https://content.doitong.com/dev-api/2026/10/20/req_8k2m4q7x1z9c3v5b6n0p2r4t/0-output.mp4",
      "content_type": "video/mp4",
      "file_name": "0-output.mp4",
      "file_size": 1843200,
      "width": 1024,
      "height": 768,
      "fps": 1.0,
      "duration": 5,
      "num_frames": 1
    },
    "seed": 42,
    "timings": {}
  },
  "outputs": [
    {
      "type": "video",
      "url": "https://content.doitong.com/dev-api/2026/10/20/req_8k2m4q7x1z9c3v5b6n0p2r4t/0-output.mp4",
      "content_type": "video/mp4",
      "file_size": 1843200,
      "width": 1280,
      "height": 720,
      "duration": 5,
      "stored": true
    }
  ],
  "error": null,
  "metrics": {
    "inference_seconds": 6.8
  },
  "urls": {
    "self": "https://api.doitong.ru/v1/requests/req_8k2m4q7x1z9c3v5b6n0p2r4t",
    "cancel": "https://api.doitong.ru/v1/requests/req_8k2m4q7x1z9c3v5b6n0p2r4t/cancel"
  }
}
Para agentes de IA: esta página en Markdown está disponible en https://doitong.com/es-MX/developers/models/blackforestlabs/flux-3-max/text-to-video.md. Todos los modelos y guías: https://doitong.com/developers/llms.txt